BLoB: Bayesian Low-Rank Adaptation by Backpropagation for Large Language Models
June 17, 2024· ,,·
0 min read
Yibin Wang
Equal contribution
,Haizhou Shi
Equal contribution
,Ligong Han
Dimitris Metaxas
Hao Wang
Abstract
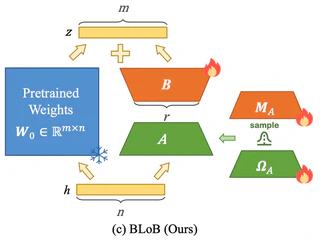
Large Language Models (LLMs) often suffer from overconfidence during inference, particularly when adapted to downstream domain-specific tasks with limited data. Previous work addresses this issue by employing approximate Bayesian estimation after the LLMs are trained, enabling them to quantify uncertainty. However, such post-training approaches’ performance is severely limited by the parameters learned during training. In this paper, we go beyond post-training Bayesianization and propose Bayesian Low-Rank Adaptation by Backpropagation (BLoB), an algorithm that continuously and jointly adjusts both the mean and covariance of LLM parameters throughout the whole fine-tuning process. Our empirical results verify the effectiveness of BLoB in terms of generalization and uncertainty estimation, when evaluated on both in-distribution and out-of-distribution data.
Type
Publication
Advances in Neural Information Processing Systems (NeurIPS), 2024

Authors
Yibin Wang
(he/him)
First-year Ph.D. student
I am a first-year Ph.D. student in the Computer Science Department at Rutgers University, where I am advised by Prof. Chengzhi Mao. I am currently studying post-training for MoE LLMs and world models. My goal is to improve model post-training through efficient, streamlined methods. I also use Bayesian approaches to enhance the trustworthiness and reliability of LLMs.
From such a gentle thing, from such a fountain of all delight, my every pain is born.
—— Michelangelo